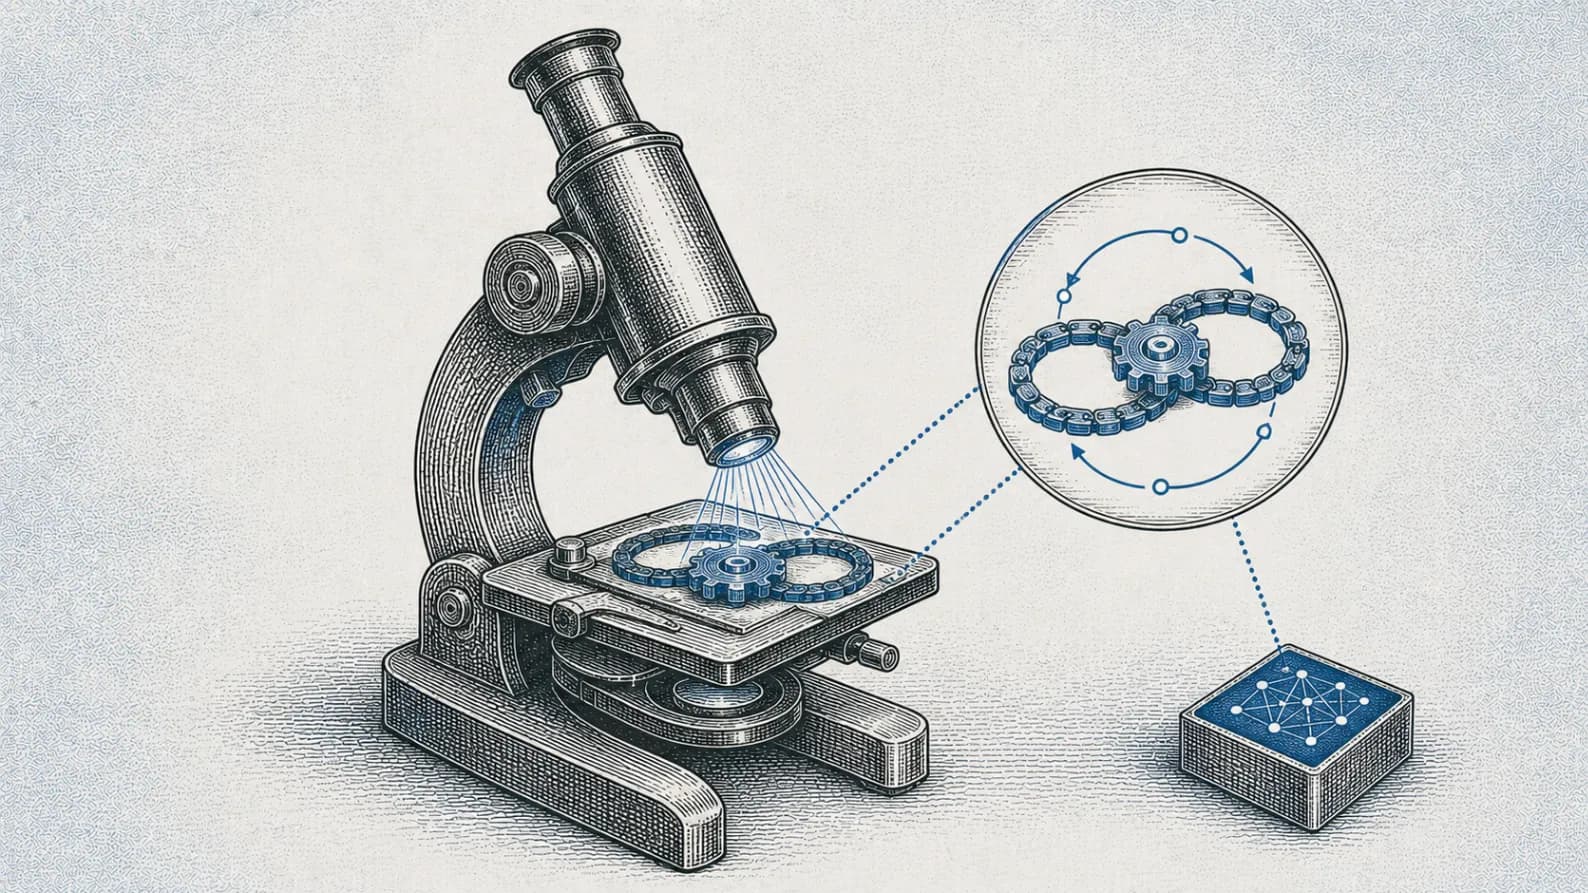
The first wave of agent development focused on what an agent could do. The next wave is focused on whether a system can identify weak behavior, learn from production evidence, and improve without turning every failure into another manual patch.
LangChain NY Meetup: Building Agents with Agents brings that conversation to Midtown Manhattan on Monday, Aug. 3, 2026. Speakers from LangChain and Clay will examine self-improving agents, durable memory updates, and the evaluation systems needed to determine whether agent behavior is actually improving.
The event brings AI engineers and builders together to explore how production systems can learn from real-world usage while remaining observable, measurable, and trustworthy.
About Building Agents with Agents
Robert Xu of LangChain will discuss how the LangChain team built a self-improving agent through LangSmith Engine. The session will examine how production traces can become durable memory updates that influence future behavior.
Jeff Barg, Vyshu Khota, and Soroush Khadem will represent Clay in a discussion of the company's agent evaluation harness and the systems used to evaluate agents with other automated components.
The agenda includes presentations, Q&A, food, drinks, and networking. That format gives builders an opportunity to move beyond architecture and into operational questions: what should be measured, which failures matter, and how teams can distinguish apparent improvement from reliable improvement.
Why Agent Evaluation Is Different
Traditional software testing begins with a useful assumption: given the same input and system state, software should produce the same output. Agent applications weaken that assumption.
Model responses vary. Tool calls fail in different ways. Context changes behavior. External systems return new information. A successful demonstration can mask weak performance across a broader range of tasks, users, and edge cases.
That does not make evaluation impossible. It changes what evaluation must capture. Teams need representative task sets, production traces, failure categories, human judgment, and repeatable scoring. They also need to determine which improvements are durable and which apparent gains simply overfit a limited benchmark.
Evaluation becomes part of the product architecture rather than a gate at the end of development.
From Traces to Durable Memory
Production traces reveal what an agent saw, which tools it selected, what it returned, and where the workflow failed. The more interesting question is what happens next.
A team can review the failure and patch a prompt. It can add another rule, rewrite a tool description, or introduce another orchestration branch. Those interventions may solve one problem while gradually increasing system complexity.
The self-improving-agent thesis is more ambitious. It asks whether production evidence can be converted into durable memory that changes future behavior without requiring developers to manually author every correction.
That introduces a new control problem. Memory updates can preserve useful experience, but they can also encode incorrect conclusions, unusual exceptions, or information that should eventually expire. Teams need provenance, review, versioning, and rollback around memory just as they do around code.
Building Agents With Agents
The event title reflects a broader market direction. AI systems are increasingly being used not only to perform work, but also to inspect, evaluate, and improve other AI systems.
An evaluation agent can classify failures across thousands of production traces. A synthetic user can probe workflows before customers encounter them. A judge model can compare outputs against a rubric, while another component proposes memory updates or identifies the tool descriptions responsible for incorrect decisions.
Those systems create leverage, but they do not eliminate the need for human judgment. Automated evaluators can be inconsistent, reward superficial fluency, or overlook business consequences. A response that scores well syntactically can still violate customer expectations or introduce operational risk.
The strongest evaluation systems combine automated coverage with deliberate human review. Automation expands the number of cases teams can inspect. People decide which failures matter.
The Operators Behind the Event
LangChain develops tooling for building, testing, deploying, and monitoring agent applications. LangSmith provides observability and evaluation infrastructure for teams operating those systems.
Clay has become a visible operator in the agent workflow market, particularly across data enrichment and go-to-market applications. Its participation brings a production perspective from a company deploying agents inside business workflows where poor data or incorrect actions can quickly propagate downstream.
Robert Xu is listed as Deployed Engineering Manager at LangChain. Clay's speakers include Jeff Barg, Head of AI; Vyshu Khota, ML Engineer; and Soroush Khadem, Software Engineer.
That combination matters because agent reliability is not solved by a single discipline. It spans model behavior, data quality, product design, application engineering, observability, and the people ultimately responsible for the workflow.
Questions Builders Should Bring
The most valuable conversation will not be about whether agents can improve. It will be about what improvement actually means.
What is the appropriate unit of evaluation: a single response, a completed task, a customer outcome, or the cost of human intervention? Which production traces should become memory or training evidence? Who approves durable behavioral changes? How does a team detect regression in behavior it was not previously measuring?
Builders should also ask what must remain reversible. If an agent learns from a noisy week of production data, can the team explain the resulting behavior and return to a known state?
Those questions transform self-improvement from a feature claim into an operating discipline.
What This Signals
The agent ecosystem is moving from capability demonstrations toward lifecycle management. Durable advantage will not come solely from building an agent that works once. It will come from creating an operating system that explains why failures occurred, what changed, and whether the next version is genuinely better.
That makes evaluation, memory, observability, and rollback foundational infrastructure for the next generation of agent platforms.
 RSYNQ Raises $2M From Kanaden for Physical AI in Japan|Homa Raises $5M Seed for AI Homebuying and Mortgages|Origin Emerges With $20M Total for Construction Robots|
 Kutlerri.ai Raises $4M for Restaurant AI Sales Agents|
 AIsa Completes Seed Extension, Total Funding Tops $9M|Sharp Performance Raises $18M for First Responder Coaching|Molagri Announces $5.8M for Precision Biopesticides|Opsin Raises $21M for Enterprise AI Agent Security|Chariot Claims Raises $10M Series A for Consumer Arbitration|Sunbound Raises $24M Series A and Acquires Richter|